
Version info: Code for this page was tested in SPSS 20.
Multinomial logistic regression is used to model nominal outcome
variables, in which the log odds of the outcomes are modeled as a linear
combination of the predictor variables.
Please note: The purpose of this page is to show how to use various
data analysis commands. It does not cover all aspects of the research process
which researchers are expected to do. In particular, it does not cover data
cleaning and checking, verification of assumptions, model diagnostics and
potential follow-up analyses.
Examples of multinomial logistic regression
Example 1. People’s occupational choices might be influenced
by their parents’ occupations and their own education level. We can study the
relationship of one’s occupation choice with education level and father’s
occupation. The occupational choices will be the outcome variable which
consists of categories of occupations.
Example 2. A biologist may be interested in food choices that alligators make. Adult alligators might have
difference preference than young ones. The outcome variable here will be the
types of food, and the predictor variables might be the length of the alligators
and other environmental variables.
Example 3. Entering high school students make program choices among general
program, vocational program and academic program. Their choice might be modeled
using their writing score and their social economic status.
Description of the data
For our data analysis example, we will expand the third example using the
hsbdemo data set. You can download the data
here.
The data set contains variables on 200 students. The outcome variable is
prog, program type. The predictor variables are social economic status,
ses, a three-level categorical variable and writing score, write, a
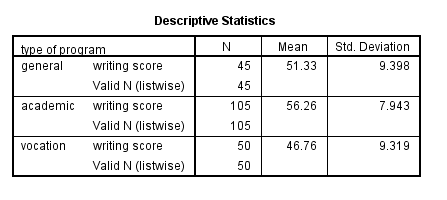
continuous variable. Let’s start with getting some descriptive statistics of the
variables of interest.
get data "D:\data\hsbdemo.sav".crosstabs /tables=prog by ses /statistics=chisq /cells=count.sort cases by prog. split file by prog. descriptives var = write /statistics = mean stddev. split file off.
Analysis methods you might consider
- Multinomial logistic regression: the focus of this page.
- Multinomial probit regression: similar to multinomial logistic
regression but with independent normal error terms. - Multiple-group discriminant function analysis: A multivariate method for
multinomial outcome variables - Multiple logistic regression analyses, one for each pair of outcomes:
One problem with this approach is that each analysis is potentially run on a
different sample. The other problem is that without constraining the
logistic models, we can end up with the probability of choosing all possible
outcome categories greater than 1. - Collapsing number of categories to two and then doing a logistic
regression: This approach suffers from loss of information and changes the
original research questions to very different ones. - Ordinal logistic regression: If the outcome variable is truly ordered
and if it also satisfies the assumption of proportional odds, then switching
to ordinal logistic regression will make the model more parsimonious. - Alternative-specific multinomial probit regression: allows different
error structures therefore allows to relax the independence of irrelevant
alternatives (IIA, see below “Things to Consider”) assumption. This requires
that the data structure be choice-specific. - Nested logit model: also relaxes the IIA assumption, also requires the
data structure be choice-specific
Using the multinomial logit model
Below we use the nomreg command to estimate a multinomial logistic
regression model. We specify the baseline comparison group to be the academic
group using (base=2).
nomreg prog (base = 2) by ses with write
/print = lrt cps mfi parameter summary.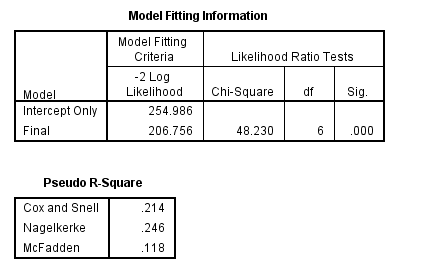
- The likelihood ratio chi-square of 48.23 with a p-value < 0.0001 tells us that our model as a whole fits
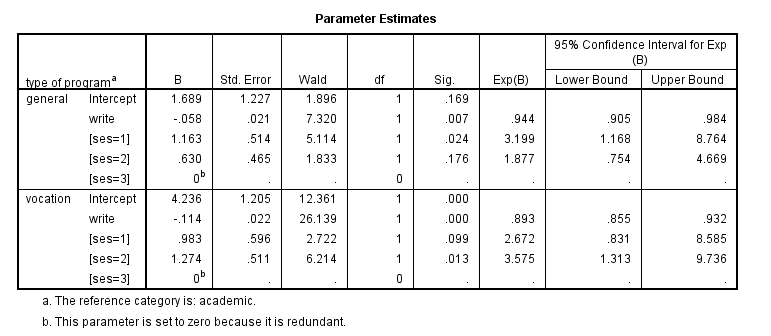
significantly better than an empty model (i.e., a model with no predictors) - The output above has two parts, labeled with the categories of the
outcome variable prog. They correspond to the two equations below:
$$ln\left(\frac{P(prog=general)}{P(prog=academic)}\right) = b_{10} + b_{11}(ses=1) + b_{12}(ses=2) + b_{13}write$$
$$ln\left(\frac{P(prog=vocation)}{P(prog=academic)}\right) = b_{20} + b_{21}(ses=1) + b_{22}(ses=2) + b_{23}write$$
where \(b\)’s are the regression coefficients.
- A one-unit increase in the variable write is associated with a
.058 decrease in the relative log odds of being in general program versus
academic program . - A one-unit increase in the variable write is associated with a
.1136 decrease in the relative log odds of being in vocation program versus
academic program. - The relative log odds of being in general program versus in academic program will
increase by 1.163 if moving from the highest level of ses (ses = 3) to the
lowest level of ses (ses = 1).
The ratio of the probability of choosing one outcome category over the
probability of choosing the baseline category is often referred to as relative risk
(and it is also sometimes referred to as odds as we have just used to described the
regression parameters above). Thus, exponentiating the linear
equations above
yields relative risks. Regression coefficients represent the change
in log relative risk (log odds) per unit change in the predictor.
Exponentiating regression coefficients will therefore yield relative
risk ratios. SPSS
includes relative risk
ratios in the output, under the column “Exp(B)”.
- The relative risk ratio for a one-unit increase in the variable write
is .9437 (exp(-.0579284) from the output of the nomreg command
above) for being in general program versus academic program. - The relative risk ratio switching from ses = 3 to 1 is 3.199 for being
in general program versus academic program. In other words, the expected risk
of staying in the general program is higher for subjects who are low in
ses.
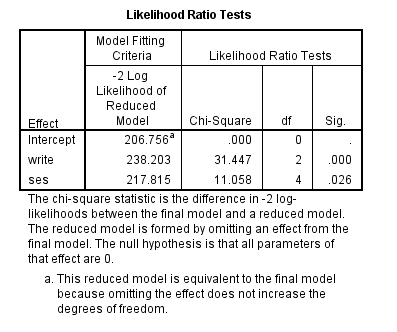
Tests for the overall effect of ses and write are outputted by
the nomreg command. Below we see that the effects are statistically
significant.
You can also use predicted probabilities to help you understand the model. You can calculate predicted probabilities using the
SPSS matrix command.
Below we calculate the predicted probability of choosing each program type at each level of
ses, holding
write at its means.
Matrix.
* intercept1 intercept2 pared public gpa.
* these coefficients are taken from the output.
compute b_gen = {1.689354 ; -0.057928 ; 1.162832 ; 0.629541}.
compute b_voc = {4.235530 ; -0.113603 ; 0.982670 ; 1.274063}.
* overall design matrix including means of public and gpa.
compute x = {{1 ; 1; 1}, make(3, 1, 52.775), {1, 0; 0, 1; 0, 0}}.
compute lp_gen = exp(x * b_gen).
compute lp_voc = exp(x * b_voc).
compute lp_aca = {1; 1; 1}.
compute p_gen = lp_gen/(lp_aca + lp_gen + lp_voc).
compute p_voc = lp_voc/(lp_aca + lp_gen + lp_voc).
compute p_aca = lp_aca/(lp_aca + lp_gen + lp_voc).
compute p = {p_gen, p_aca, p_voc}.
print p /title 'Predicted Probabilities for Outcomes 1 2 3 for ses 1 2 3 at mean of write'.
End Matrix.

Run MATRIX procedure:

Predicted Probabilities for Outcomes 1 2 3 for ses 1 2 3 at mean of write
   .3581989665   .4396824687   .2021185647
   .2283388262   .4777491509   .2939120229
   .1784967500   .7009009604   .1206022896

------ END MATRIX -----
Column 1 contains the predicted probabilities for prog = general, where ses equals 1, 2 and 3 on each successive row. Columns 2 and 3 are the same for prog = academic and prog = vocational, respectively. We can also calculate predicted probabilities as we vary write from 30 to 70, when ses = 1.
Matrix.
* intercept1 intercept2 pared public gpa.
* these coefficients are taken from the output.
compute b_gen = {1.689354 ; -0.057928 ; 1.162832 ; 0.629541}.
compute b_voc = {4.235530 ; -0.113603 ; 0.982670 ; 1.274063}.
* overall design matrix including means of public and gpa.
compute x = {make(5,1,1), {30; 40; 50; 60; 70}, make(5,1,1), make(5,1,0)}.
compute lp_gen = exp(x * b_gen).
compute lp_voc = exp(x * b_voc).
compute lp_aca = {1; 1; 1; 1; 1}.
compute p_gen = lp_gen/(lp_aca + lp_gen + lp_voc).
compute p_voc = lp_voc/(lp_aca + lp_gen + lp_voc).
compute p_aca = lp_aca/(lp_aca + lp_gen + lp_voc).
compute p = {p_gen, p_aca, p_voc}.
print p /title 'Predicted Probabilities for Outcomes 1 2 3 for write 30 40 50 60 70 at ses=1'.
End Matrix.

Run MATRIX procedure:

Predicted Probabilities for Outcomes 1 2 3 for write 30 40 50 60 70 at ses=1
   .2999966732   .0984378501   .6015654767
   .3656613530   .2141424912   .4201961559
   .3698577661   .3865775582   .2435646757
   .3083735022   .5752505689   .1163759289
   .2199925775   .7324300249   .0475773976

------ END MATRIX -----
Column 1 contains the predicted probabilities for prog = general, where write equals 30, 40, 50, 60 and 70 for rows 1 through 5, respectively. Columns 2 and 3 are the same for prog = academic and prog = vocational, respectively.
Things to consider
- The independence of irrelevant alternatives (IIA) assumption: roughly,
the IIA assumption means that adding or deleting alternative outcome
categories does not affect the odds among the remaining outcomes. There are alternative modeling methods
that relax the IIA assumption,
such as alternative-specific multinomial probit models or nested logit
models. - Diagnostics and model fit: unlike logistic regression where there are
many statistics for performing model diagnostics, it is not as
straightforward to do diagnostics with multinomial logistic regression
models.
For the purpose of detecting outliers or influential data points, one can
run separate logistic regression models and use the diagnostics tools on each model. - Pseudo-R-Squared: the R-squared offered in the output is basically the
change in terms of log-likelihood from the intercept-only model to the
current model. It does not convey the same information as the R-square for
linear regression, even though it is still “the higher, the better”. - Sample size: multinomial regression uses a maximum likelihood estimation
method, it requires a large sample size. It also uses multiple
equations. This implies that it requires an even larger sample size than ordinal or
binary logistic regression. - Complete or quasi-complete separation: Complete separation implies that
the outcome variable separates a predictor variable completely, leading to
perfect prediction by the predictor variable. Perfect prediction means that only one value of a predictor
variable is associated with only one value of the response variable. But you can tell from the output of the
regression coefficients that something is wrong. You can then do a two-way tabulation of the outcome
variable with the problematic variable to confirm this and then rerun the model
without the problematic variable. - Empty cells or small cells: You should check for empty or small
cells by doing a cross-tabulation between categorical predictors and
the outcome variable. If a cell has very few cases (a small cell), the
model may become unstable or it might not even run at all. - Perhaps your data may not perfectly meet the assumptions and your
standard errors might be off the mark. - Sometimes observations are clustered into groups (e.g., people within
families, students within classrooms). In such cases, this is not an
appropriate analysis.
See also
- SPSS Annotated Output: Multinomial
Logistic Regression - Applied Logistic Regression (Second
Edition) by David Hosmer and Stanley Lemeshow - An Introduction to Categorical Data
Analysis by Alan Agresti
References
- Long, J. S. and Freese, J. (2006)
Regression Models
for Categorical and Limited Dependent Variables Using Stata, Second Edition.
College Station, Texas: Stata Press. - Hosmer, D. and Lemeshow, S. (2000)
Applied
Logistic Regression (Second Edition). New York: John Wiley & Sons, Inc.. - Agresti, A. (1996)
An
Introduction to Categorical Data Analysis. New York: John Wiley & Sons,
Inc.