
Poisson regression is used to model count variables.
Please note: The purpose of this page is to show how to use various
data analysis commands. It does not cover all aspects of the research process
which researchers are expected to do. In particular, it does not cover data
cleaning and checking, verification of assumptions, model diagnostics or
potential follow-up analyses.
This page is done using SPSS 19.
Examples of Poisson regression
Example 1. The number of persons killed by mule or horse kicks in the
Prussian army per year. Ladislaus Bortkiewicz collected data from 20 volumes of
Preussischen Statistik. These data were collected on 10 corps of the
Prussian army in the late 1800s over the course of 20 years.
Example 2. The number of people in line in front of you at the grocery
store. Predictors may include the number of items currently offered at a
special discounted price and whether a special event (e.g., a holiday, a big
sporting event) is three or fewer days away.
Example 3. The number of awards earned by students at one high school.
Predictors of the number of awards earned include the type of program in which
the student was enrolled (e.g., vocational, general or academic) and the score
on their final exam in math.
Description of the Data
For the purpose of illustration, we have simulated a data set for Example 3
above: https://stats.idre.ucla.edu/wp-content/uploads/2016/02/poisson_sim.sav. In this example,
num_awards is the outcome variable and indicates the number of awards earned
by students at a high school in a year, math is a continuous predictor
variable and represents students’ scores on their math final exam, and prog
is a categorical predictor variable with three levels indicating the type of
program in which the students were enrolled.
Let’s start with loading the data and looking at some descriptive statistics.
GET
  FILE='D:\data\poisson_sim.sav'.

  DESCRIPTIVES
  VARIABLES=math num_awards
  /STATISTICS=MEAN STDDEV VAR MIN MAX .
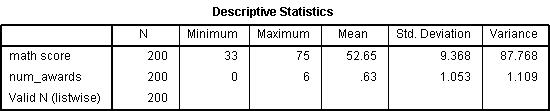
Each variable has 200 valid observations and their distributions seem quite
reasonable. The unconditional mean and variance of our outcome variable
are not extremely different. Our model assumes that these values, conditioned on
the predictor variables, will be equal (or at least roughly so).
Let’s continue with our description of the variables in this dataset. The
table below shows the average numbers of awards by program type and seems to
suggest that program type is a good candidate for predicting the number of
awards, our outcome variable, because the mean value of the outcome appears to
vary by prog. Additionally, the means and variances within each level of
prog–the conditional means and variances–are similar.
MEANS tables = num_awards by prog.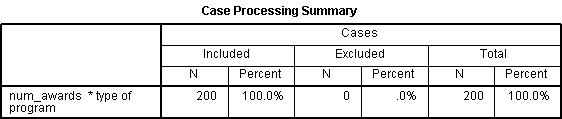
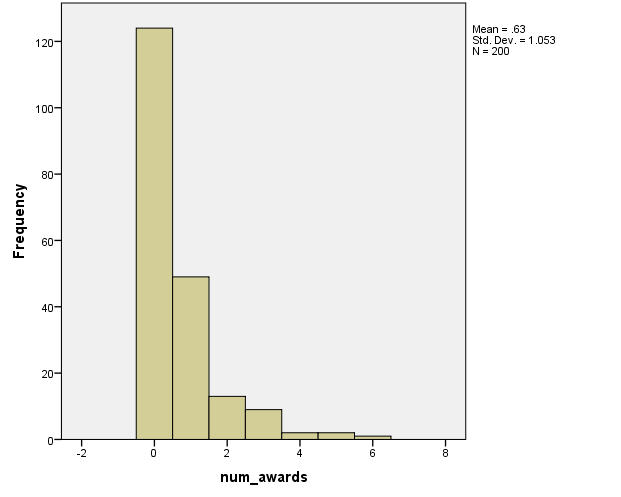
GRAPH /HISTOGRAM=num_awards.
Analysis methods you might consider
Below is a list of some analysis methods you may have
encountered. Some of the methods listed are quite reasonable, while others have
either fallen out of favor or have limitations.
- Poisson regression – Poisson regression is often used for modeling count
data. It has a number of extensions useful for count models. - Negative binomial regression – Negative binomial regression can be used
for over-dispersed count data, that is when the conditional variance exceeds
the conditional mean. It can be considered as a generalization of Poisson
regression since it has the same mean structure as Poisson regression and it
has an extra parameter to model the over-dispersion. If the
conditional distribution of the outcome variable is over-dispersed, the
confidence intervals for Negative binomial regression are likely to be
narrower as compared to those from a Poisson regession. - Zero-inflated regression model – Zero-inflated models attempt to account
for excess zeros. In other words, two kinds of zeros are thought to exist
in the data, “true zeros” and “excess zeros”. Zero-inflated models estimate
two equations simultaneously, one for the count model and one for the excess
zeros. - OLS regression – Count outcome variables are sometimes log-transformed
and analyzed using OLS regression. Many issues arise with this approach,
including loss of data due to undefined values generated by taking the log
of zero (which is undefined) and biased estimates.
Poisson regression
Below we use the genlin command to estimate a Poisson regression
model. We have one continuous predictor and one categorical predictor. In the
genlin line, we list our categorical predictor prog after “by” and
our continuous predictor math after “with”. Both appear in the model
line. We use the covb=robust option in the criteria line to obtain robust standard errors
for the parameter estimates as recommended by Cameron and Trivedi (2009) to
control for mild violation of the distribution assumption that the variance
equals the mean. Finally, we ask SPSS to print out the model fit statistics, the
summary of the model effects, and the parameter estimates.
GENLIN num_awards BY prog WITH math
  /MODEL prog math INTERCEPT=YES
   DISTRIBUTION=POISSON LINK=LOG
  /CRITERIA COVB=ROBUST
  /PRINT FIT SUMMARY SOLUTION.
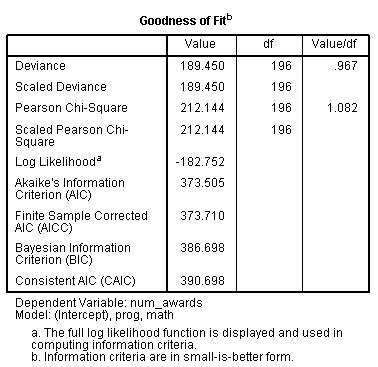
- The output begins with the Goodness of Fit table. This lists various
statistics indicating model fit. To assess the fit of the model, the goodness-of-fit chi-squared test
is provided in the first line of this table. We evaluate the deviance
(189.45) as Chi-square distributed with the model degrees of freedom (196). This is not a test of the model
coefficients (which we saw in the header information), but a test of the model
form: Does the Poisson model form fit our data? We conclude that the model fits reasonably well because the goodness-of-fit
chi-squared test is not statistically significant (with 196 degrees of freedom, p = 0.204). If the test had been
statistically significant, it would indicate that the data do not fit the model
well. In that situation, we may try to determine if there are omitted predictor
variables, if our linearity assumption holds and/or if there is an issue of
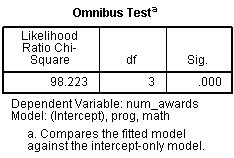
over-dispersion. - Next we see the Omnibus Test. This is a test that
all of the estimated coefficients are equal to zero–a test of the model
as a whole. From the p-value, we can see that the model is statistically
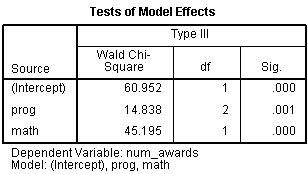
significant. - Next is the Tests of Model Effects. This evaluates each of the model
variables with the appropriate degrees of freedom. The prog variable
is categorical with three levels. Thus, it will appear in the model as two
one degree-of-freedom indicator variables. To assess the significance of
prog as a variable, we need to test these two dummy variables together in a two degree-of-freedom chi-square test.
This indicates that prog is a statistically significant predictor of num_awards.
The continuous predictor variable math requires one degree-of-freedom
in the model, and so the test presented here is equivalent to that in the
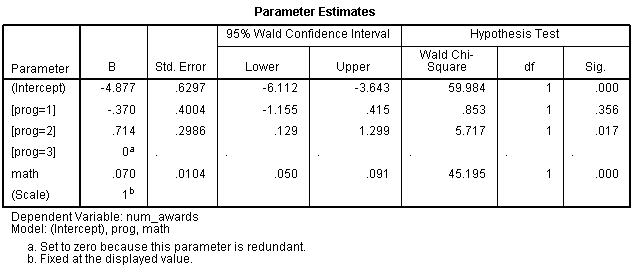
Parameter Estimates output. - Next, we see the Parameter Estimates. This includes the regression
coefficients for each of the variables along with robust standard errors,
p-values and 95% confidence intervals for the coefficients. The
coefficient for
math is 0.07. This means that the expected increase in log count for a
one-unit increase in math
is .07. The indicator variable [prog=1]
is the expected difference in log count between group 1 and
the reference group [prog=3]. Compared to level 3 of prog,
the expected log count for level 1 of
prog decreases by about 0.37.
The indicator variable [prog=2] is the expected difference in log count
between group 2 and the reference group.
Compared to level 3 of prog, the expected log count for level 2 of
prog increases by about .71. We saw from the Tests of Model
Effects output that prog,
overall, is statistically significant.
Sometimes, we might want to present the regression results as incident rate
ratios. These IRR values are equal to our
coefficients from the output above exponentiated and we can ask SPSS to print
solution(exponentiated).
GENLIN num_awards BY prog WITH math
  /MODEL prog math INTERCEPT=YES
  DISTRIBUTION=POISSON LINK=LOG
  /CRITERIA METHOD=FISHER(1) SCALE=1 COVB=ROBUST
  /PRINT SOLUTION (EXPONENTIATED).
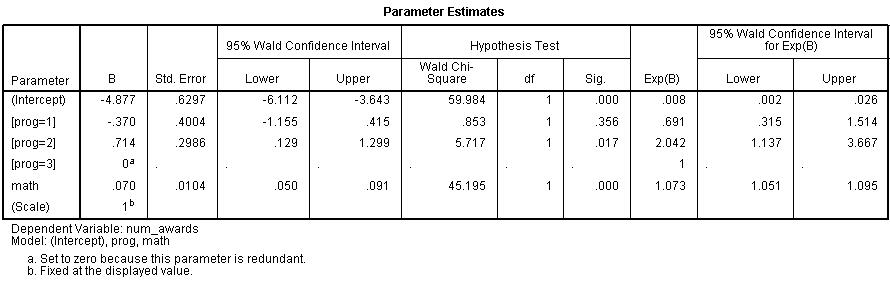
The output above indicates that the incident rate for [prog=2] is 2.042
times the incident rate for the reference group, [prog=3]. Likewise, the
incident rate for [prog=1] is 0.691 times the incident rate for the
reference group holding the other variables at constant. The percent change in
the incident rate of num_awards is an increase of 7% for every unit increase in
math.
Recall the form of our model equation:
log(num_awards) = Intercept + b1(prog=1) + b2(prog=2)
+ b3math.
This implies:
num_awards = exp(Intercept + b1(prog=1) + b2(prog=2)+
b3math) = exp(Intercept) * exp(b1(prog=1)) * exp(b2(prog=2))
* exp(b3math)
The coefficients have an additive effect in the log(y) scale and the
IRR have a multiplicative effect in the y scale.
For additional information on the various metrics in which the results can be
presented, and the interpretation of such, please see Regression Models for
Categorical Dependent Variables Using Stata, Second Edition by J. Scott Long
and Jeremy Freese (2006).
To understand the model better, we can use the
emmeans command to calculate the predicted counts at each
level of prog, holding all other variables (in this example,
math)
in the model at their means.
GENLIN num_awards BY prog WITH math
  /MODEL prog math INTERCEPT=YES
  DISTRIBUTION=POISSON LINK=LOG
  /CRITERIA METHOD=FISHER(1) SCALE=1 COVB=ROBUST
  /PRINT NONE
  /EMMEANS TABLES=prog SCALE=ORIGINAL.
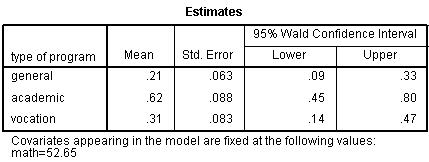
In the output above, we see that the predicted number of events for level 1
of prog is about .21, holding math at its mean. The predicted
number of events for level 2 of prog is higher at .62, and the predicted
number of events for level 3 of prog is about .31. Note that the
predicted count of level 2 of prog is (.62/.31) = 2.0 times
higher than the predicted count for level 3 of prog. This matches what we
saw in the IRR output table.
Below we will obtain the predicted counts for each value of prog at
two set values of math: 35 and 75.
GENLIN num_awards BY prog WITH math /MODEL prog math INTERCEPT=YES DISTRIBUTION=POISSON LINK=LOG /PRINT NONE /EMMEANS TABLES=prog CONTROL =math(35) SCALE=ORIGINAL.GENLIN num_awards BY prog WITH math /MODEL prog math INTERCEPT=YES DISTRIBUTION=POISSON LINK=LOG /PRINT NONE /EMMEANS TABLES=prog CONTROL =math(75) SCALE=ORIGINAL.
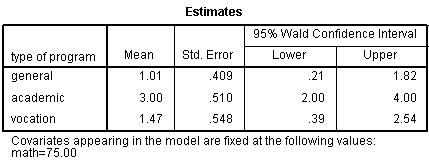
The table above shows that with prog=1 and
math held at 35, the average predicted count (or
average number of awards) is about .06; when math = 75, the average
predicted count for prog=1 is about 1.01. If we look at these predicted counts at math = 35
and math = 75, we can see that the ratio is (1.01/0.06) = 16.8. This
matches (within rounding error) the IRR of 1.0727 for a 40 unit change: 1.0727^40 =
16.1.
Things to consider
- When there seems to be an issue of dispersion, we should first check if
our model is appropriately specified, such as omitted variables and
functional forms. For example, if we omitted the predictor variable prog
in the example above, our model would seem to have a problem with
over-dispersion. In other words, a mis-specified model could present a
symptom like an over-dispersion problem. - Assuming that the model is correctly specified, you may want to
check for overdispersion.
There are several tests including the likelihood ratio test of
over-dispersion parameter alpha by running the same regression model using
negative binomial distribution (distribution = negbin). - One common cause of over-dispersion is excess zeros, which in turn are
generated by an additional data generating process. In this situation,
zero-inflated model should be considered. - If the data generating process does not allow for any 0s (such as the
number of days spent in the hospital), then a zero-truncated model may be
more appropriate. - The outcome variable in a Poisson regression cannot have negative
numbers. - Poisson regression is estimated via maximum likelihood estimation. It
usually requires a large sample size.
See also
-
- SPSS Annotated
Output: Poisson Regression - References
- Long, J. S. 1997.
- SPSS Annotated
Regression Models for Categorical and Limited Dependent Variables.
-
-
- Thousand Oaks, CA: Sage Publications.
-
References
- Cameron, A. C. and Trivedi, P. K. 2009. Microeconometrics Using
Stata. College Station, TX: Stata Press. - Cameron, A. C. and Trivedi, P. K. 1998. Regression Analysis of
Count Data. New York: Cambridge Press. - Cameron, A. C. Advances in Count Data Regression Talk for the Applied
Statistics Workshop, March 28, 2009.
http://cameron.econ.ucdavis.edu/racd/count.html . - Dupont, W. D. 2002. Statistical Modeling for Biomedical
Researchers: A Simple Introduction to the Analysis of Complex Data.
New York: Cambridge Press. - Long, J. S. 1997. Regression Models for Categorical and Limited
Dependent Variables. Thousand Oaks, CA: Sage Publications. - Long, J. S. and Freese, J. 2006. Regression Models for Categorical
Dependent Variables Using Stata, Second Edition. College Station, TX:
Stata Press.